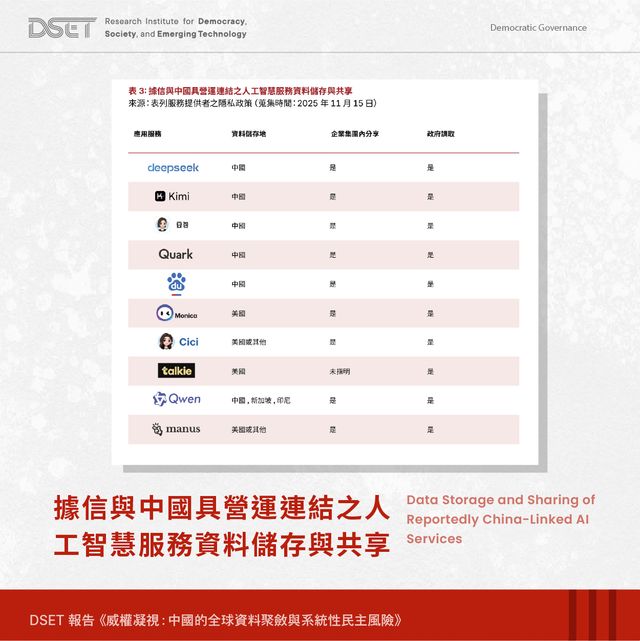
The review of the Chinese Internet, after a long period of censorship, left more than “404 pages”. It is entering the global AI system in the form of training data. The latest study by the Taiwan Centre for Science, Technology, Democracy and Social Research (DSET) conducted a cross-language test of ChatGPT-5.2 and Gemini 3, finding that the response of the same model in the Chinese-language environment is more likely to be marked by a narrative deviation similar to that of the Chinese censorship system than the English-language environment.
This finding is more alarming than “an AI refuses to answer the Tiananmen Gate”, because it reveals not a visible wall of closure, but a structural deviation from the knowledge base that is permanently screened.
2400 responses indicated that language itself changed the world given by AI
The research team, in February-March 2026, compared 300 politically sensitive and 100 natural science words that might be reviewed by the CPC, in English, Chinese and Chinese, ChatGPT-5.2 and Gemini 3, respectively, obtained 2,400 answers, and tested the review deviations using the multilingual classificationer RedactIQ-XLM 1.0.
The results show that, among politically sensitive questions, Gemini responded with a percentage of review deviations, 13.1 per cent in Chinese, 9.2 per cent in Chinese and 0 per cent in English; The corresponding ratios for ChatGPT were 6.9 per cent, 6.3 per cent and 0.7 per cent.
The most critical variable is not whether the user is in Beijing, Taipei or New York, but in what language the user asks questions. Chinese is not automatically free from the influence of the language under review because it serves mainly Chinese users in Taiwan, Hong Kong and overseas.
The most dangerous is not a refusal, but a “normal answer” you can't see
When the public spoke of the Chinese-style AI review, it was easy to think of a model that said, “I cannot answer this question”. DSET studies have found that real-visibility biases are found in a large number of seemingly less sensitive themes, such as the economy, the environment and so on.
For example, in Chinese, when asking about the food shortage in China, the model is more easily brought into the official Chinese slogans and policy statements; The same text, in English, is used to ask questions, but the political languages may disappear.
This means that the most efficient form of review is not to delete the answer, but to change what is most easily considered by the model as “normal knowledge”. The statistical distribution of training materials has been skewed when a large number of Chinese materials that have been deleted, reduced or are not available for long have disappeared from the open network, while content from official media, government websites and reviewed platforms has been extensively preserved and crawled out.
The model is not necessarily instructed to “advocacy for the CCP”, but it may still learn from the purified reality of the Chinese-language world.
原始来源 · dset.tw「清朗」AI:西方语言模型的中国审查渗入dset.tw ↗The review of the Chinese Communist Party began to produce a typologies of transnational and cross-platform effects
The Chinese network review was primarily understood as the control of information flows in China: redacting, sealing, keyword shielding, search and downfall rights, and media directives. But the big language model changed the boundary.
Global AI training models require a big web-based text. In Chinese, the content that can be steadily captured and stored for long periods of time has itself been screened for years by the Chinese information governance system. Thus, the CCP does not need to directly control an American AI company, or may indirectly influence what future models learn by controlling the “visibility” of the Chinese-language network.
This is an information pollution spill mechanism: to control the original language and then allow the global model to unwittingly inherit the gap in the language.
The real need for AI is where the Chinese data came from.
The solution cannot stop at requiring the model to be “neutral”. If the deviations are from training data, simply adjusting the answers cannot repair the knowledge structure.
The direction proposed by DSET includes expanding Chinese language training materials that have not been reviewed by China, disclosing data sources, establishing a knowledge base in Chinese that can be validated, and using search enhancement to enable models to access more complete materials in their responses to China ' s political, economic and social problems.
Here is a more fundamental question of transparency: the public in Chinese has the right to know how much knowledge a model has in China comes from Chinese officials, the centuric, the commercial platform under review, and how many from independent media, academic databases, overseas Chinese materials, and historical materials have been removed from China’s network.
If the developers are unable to answer this question, the so-called “AI neutrality” can only be an unverifiable self-declaration.
The next phase of the firewall may not be required
Traditional web censorship is blinding. The risks of the generation of AI are more subtle: users see complete, fluid and grammatical answers, and are therefore more easily seen as integrated knowledge.
When the model omits something that coincides with something that was deleted from the real network, the review goes from "not reading you" to "summarizing a world that you have been screened for."
That is the real question that the DSET report raises. The CCP ' s information control capacity does not need to have ChatGPT or Gemini, but may also have access to these systems by long-term shaping the Chinese Internet training environment. The future competition around AI and China’s censorship will not be the only one whose core model is stronger, but who can preserve more Chinese facts that are not pre-cleaned by power.
Article discussion
Verified members can discuss this report publicly and manage their own content.
Checking member sign-in status…